
During an incident, a Kafka dashboard shows more charts than anyone on call can read. Kafka keeps a copy of many metrics per topic, partition, client and request type, and the few that say something is failing sit among thousands that only describe the cluster.
The alerts worth waking someone for answer plainer questions: can producers write, are the replicas safe, are the brokers keeping up, will the disks last, do consumers keep up. Everything else helps the investigation once an alert fires.
On a KRaft cluster, some of the answers don't come from the brokers at all.
Kafka Metrics to Alert On
Each MBean below was read over JMX on Kafka 4.3.1 in KRaft mode. Thresholds come from the Apache Kafka monitoring docs where they exist; the rest alert against your own baseline:
| # | Metric | What it tells you | Alert when | MBean or source |
|---|---|---|---|---|
| 1 | Under-replicated partitions | A replica left the ISR | Above 0 beyond a restart | kafka.server:type=ReplicaManager,name=UnderReplicatedPartitions |
| 2 | Under min ISR | acks=all writes fail | Above 0 | kafka.server:type=ReplicaManager,name=UnderMinIsrPartitionCount |
| 3 | Offline partitions | No leader: no reads, no writes | Above 0 | kafka.controller:type=KafkaController,name=OfflinePartitionsCount |
| 4 | Active controller | One controller runs the metadata | Sum across controllers isn't 1 | kafka.controller:type=KafkaController,name=ActiveControllerCount |
| 5 | ISR shrinks | A live follower fell behind | Above 0 | kafka.server:type=ReplicaManager,name=IsrShrinksPerSec |
| 6 | Thread idle ratios | Spare I/O and network threads | Below 0.3 | kafka.server:type=KafkaRequestHandlerPool,name=RequestHandlerAvgIdlePercent and kafka.network:type=SocketServer,name=NetworkProcessorAvgIdlePercent |
| 7 | Produce request time | Write latency in the broker | p99 above baseline | kafka.network:type=RequestMetrics,name=TotalTimeMs,request=Produce |
| 8 | Bytes in and out | Load per broker and topic | A step against baseline | kafka.server:type=BrokerTopicMetrics,name=BytesInPerSec and BytesOutPerSec |
| 9 | Free disk | Days until the disk fills | Fewer days than a fix takes | Host volume metric; kafka.log:type=Log,name=Size |
| 10 | Consumer lag | Backlog per consumer group | Growing, or past the group's SLA | Log end offset minus committed offset |
"All levels of alerts are in Zabbix. And only the highest levels of alerts go to PagerDuty."
Operations team lead at a healthcare software company
They don't all come from the brokers. Since KRaft, offline partitions and the active controller exist only on the controllers, free disk comes from the host, and lag from each group's committed offsets:
The glossary entry on cluster monitoring covers the JMX exporter and Prometheus setup. Setting up the alerts takes these steps:
- Page on
UnderMinIsrPartitionCount. Withmin.insync.replicasat 2, it fires whenacks=allwrites start failing, before any partition goes offline. - Scrape the KRaft controllers. With dedicated KRaft controllers, brokers register no
kafka.controllerMBeans. - Warn on idle threads and p99. Produce time grows when a thread pool runs short of idle time.
- Alert on disk time left. A broker whose only log directory fills shuts down.
- Read lag from committed offsets. The broker keeps them after the consumer stops.
- Route each alert to an owner. Lag goes to the team that runs the consumer.
Page on UnderMinIsrPartitionCount
Page when UnderMinIsrPartitionCount or OfflinePartitionsCount goes above 0, and when UnderReplicatedPartitions stays above 0 longer than a broker restart.
A partition has a leader and followers. The followers that have caught up with the leader form the in-sync replica set, the ISR (replication primer).
min.insync.replicas sets how many of them must hold a write before an acks=all producer gets its acknowledgement. Three metrics count partitions by how far the ISR has shrunk:
min.insync.replicas=2. Under min ISR is the first state where acks=all producers get errors.Each broker counts only the partitions it leads, so sum across brokers. With one broker of three stopped, broker 2 reported 28 under-replicated partitions, its whole LeaderCount. A rolling restart produces the same count. The count names no topic: kafka-topics.sh --describe --under-replicated-partitions lists the partitions.
🚫 "Offline partitions are at zero, so every topic accepts writes."
With two of three brokers stopped and min.insync.replicas=2 on orders, every partition kept a leader and the controller counted zero offline partitions. Producers using acks=all got errors, and the broker counted them by error code:
# broker 2, with brokers 3 and 4 stopped
kafka.server:type=ReplicaManager,name=UnderReplicatedPartitions:Value=56
kafka.server:type=ReplicaManager,name=UnderMinIsrPartitionCount:Value=6
# controller
kafka.controller:type=KafkaController,name=OfflinePartitionsCount:Value=0
# console producer, acks=all
org.apache.kafka.common.errors.NotEnoughReplicasException: Messages are rejected since there are fewer in-sync replicas than required.
# broker 2
kafka.network:type=RequestMetrics,name=ErrorsPerSec,request=Produce,error=NOT_ENOUGH_REPLICAS:Count=4
The same write with acks=1 went through. With min.insync.replicas at 2 or more, UnderMinIsrPartitionCount fires before any partition goes offline; at the default of 1 it never fires, because a leader always counts in its own ISR.
With unclean.leader.election.enable at its default, false, an offline partition waits for an in-sync replica. UncleanLeaderElectionsPerSec on the controller counts the elections that didn't wait, each losing writes, and should stay at 0.
Scrape the KRaft Controllers
Add the controller nodes to whatever scrapes the brokers. With ZooKeeper, every broker registered the kafka.controller MBeans. On KRaft with dedicated controllers, brokers register none:
# broker 2
$ kafka-jmx.sh --jmx-url service:jmx:rmi:///jndi/rmi://localhost:9999/jmxrmi \
    --object-name 'kafka.controller:*' --one-time true --report-format properties
No matched attributes for the queried objects [kafka.controller:*].

# controller 1, same command
$ kafka-jmx.sh ... | grep -E 'ControllerCount|BrokerCount|OfflinePartitionsCount|Unclean.*:Count'
kafka.controller:type=ControllerStats,name=UncleanLeaderElectionsPerSec:Count=0
kafka.controller:type=KafkaController,name=ActiveBrokerCount:Value=3
kafka.controller:type=KafkaController,name=ActiveControllerCount:Value=1
kafka.controller:type=KafkaController,name=ControlledShutdownBrokerCount:Value=0
kafka.controller:type=KafkaController,name=FencedBrokerCount:Value=0
kafka.controller:type=KafkaController,name=OfflinePartitionsCount:Value=0
An exporter that scrapes only brokers misses ActiveControllerCount and OfflinePartitionsCount. Alert when ActiveControllerCount summed across the controllers isn't 1 or when their series stop: a controller that's down reports nothing.
On KRaft, IsrShrinksPerSec doesn't count a broker going down. Stopping broker 4, then pausing its container under load, left the rate at 0 on the other brokers while their ISRs shrank.
The controller removed broker 4 itself, on its shutdown notice or after broker.session.timeout.ms (9 seconds) without a heartbeat, and FencedBrokerCount went to 1.
Leaders shrink the ISR themselves only when a live follower falls replica.lag.time.max.ms (30 seconds) behind, so a non-zero rate points at a slow broker.
Warn on Idle Threads and p99
Warn when either thread idle ratio drops below 0.3 or produce p99 climbs above its baseline.
A request passes through two thread pools: a network thread reads it, an I/O thread (the request handler) reads or appends to the log, and a network thread sends the response.
An acks=all produce also waits in purgatory until the followers copy it. TotalTimeMs adds up the time of each phase:
RequestHandlerAvgIdlePercent and NetworkProcessorAvgIdlePercent give the idle share of the I/O threads (num.io.threads, 8 by default) and the network threads (num.network.threads, 3).
Skip RequestQueueSize: it can't pass queued.max.requests (500 by default), where the network threads block, and the wait shows in RequestQueueTimeMs. At 20,000 records per second with acks=all, broker 2 had idle threads to spare, and most of its produce p99 was the follower wait:
kafka.network:type=RequestMetrics,name=TotalTimeMs,request=Produce:99thPercentile=3.0
kafka.network:type=RequestMetrics,name=RequestQueueTimeMs,request=Produce:99thPercentile=0.0
kafka.network:type=RequestMetrics,name=LocalTimeMs,request=Produce:99thPercentile=1.0
kafka.network:type=RequestMetrics,name=RemoteTimeMs,request=Produce:99thPercentile=2.0
kafka.server:type=KafkaRequestHandlerPool,name=RequestHandlerAvgIdlePercent:OneMinuteRate=0.9993027851613767
kafka.network:type=SocketServer,name=NetworkProcessorAvgIdlePercent:Value=0.9995953500394011
The producer's own p99 in that run was 19 ms against the broker's 3 ms. The broker doesn't time batching, buffering, the network or consumer processing, so measure end-to-end latency with client metrics or tracing.
Keep fetch time out of the alert. With a consumer at zero lag and no new data, FetchConsumer p99 was 501 ms and FetchFollower 504 ms.
The broker holds a fetch open up to fetch.max.wait.ms (500 ms by default, replica.fetch.wait.max.ms for followers) and counts the wait in RemoteTimeMs.
Alert on Disk Time Left
When the disk fills before retention deletes old segments, the append fails, the broker takes the log directory offline, and a broker with one log directory shuts down. Filling a 96 MB volume:
ERROR Error while appending records to fill-0 in dir /tmp/kraft-combined-logs (org.apache.kafka.storage.internals.log.LogDirFailureChannel)
java.io.IOException: No space left on device
ERROR Shutdown broker because all log dirs in /tmp/kraft-combined-logs have failed (kafka.log.LogManager)
Producers got KAFKA_STORAGE_ERROR until the broker stopped. JMX has no free-space metric: kafka.log:type=Log,name=Size gives partition sizes, and free space comes from the host (node_exporter, cloud volume metrics) or from the Admin API's describeLogDirs, which returns usable bytes per log directory.
Alert on time left. A disk grows with BytesInPerSec for the partitions the broker leads plus ReplicationBytesInPerSec for those it follows, minus what retention deletes.
Say it grows 100 GB a day with 1 TB free: that's ten days left. Alert while the days left still exceed the time it takes to add disk or cut retention.
Per topic, bytes in falling to zero on a busy topic means its producers stopped; a step in bytes out can mean a group reset its offsets.
Read Lag From Committed Offsets
A consumer group commits, per partition, the offset of the next record it will process. Consumer lag is the distance from there to the log end offset, the end of the partition as consumers see it.
The broker stores both, so lag stays readable after the consumer stops:
$ kafka-consumer-groups.sh --bootstrap-server localhost:9092 --describe --group billing

Consumer group 'billing' has no active members.

GROUP           TOPIC           PARTITION  CURRENT-OFFSET  LOG-END-OFFSET  LAG             CONSUMER-ID     HOST            CLIENT-ID
billing         orders          0          196677          216204          19527           -               -               -
billing         orders          1          191079          214319          23240           -               -               -
billing         orders          2          196436          215056          18620           -               -               -
The consumer's own records-lag-max, under kafka.consumer:type=consumer-fetch-manager-metrics, measures from its fetch position (the Apache docs: "based on current offset and not committed offset"). It lives in the consumer's JVM, so it disappears when the consumer crashes:
Alert from committed offsets, through a lag exporter or your platform's integration (lag tools compared), and keep records-lag-max for tuning the client. How to read the number depends on the consumer:
- Real-time consumers. Lag should stay near zero; sustained lag means too little capacity, repeated rebalances or a slow downstream call.
- Batch consumers. Say a report runs every six hours. Lag climbs between runs by design, so alert when it doesn't return to zero after one.
- Trends. 500,000 behind and stable is keeping up; 5,000 behind and growing 1,000 a minute passes a million in about 16 hours.
- Partitions. Nine partitions at zero and one at 100,000 average 10,000, so alert per partition. A record the consumer can't deserialize shows up as lag on one partition.
- Time. Time lag expresses the backlog in seconds, which you can compare to an SLA (thresholds by workload).
Route Each Alert to an Owner
Route lag to the team that runs the consumer and partition alerts to the platform team, each with a runbook (alert routing, ownership questions). A group name doesn't say which team runs the consumer, and when the group has no owner, the alert reaches everyone:
"some teams, consumer groups got backed up. And then I made an announcement, hey, everyone check your consumer groups."
Senior software engineer at a retailer
Kafka Monitoring in Console
Conduktor Console collects most of these metrics: offline, under-replicated and under-min-ISR partitions, active brokers and controllers, disk usage, topic throughput, and lag per partition in records and estimated seconds (metrics). Thread idle ratios and request time aren't in Console's metrics, so keep JMX for those.
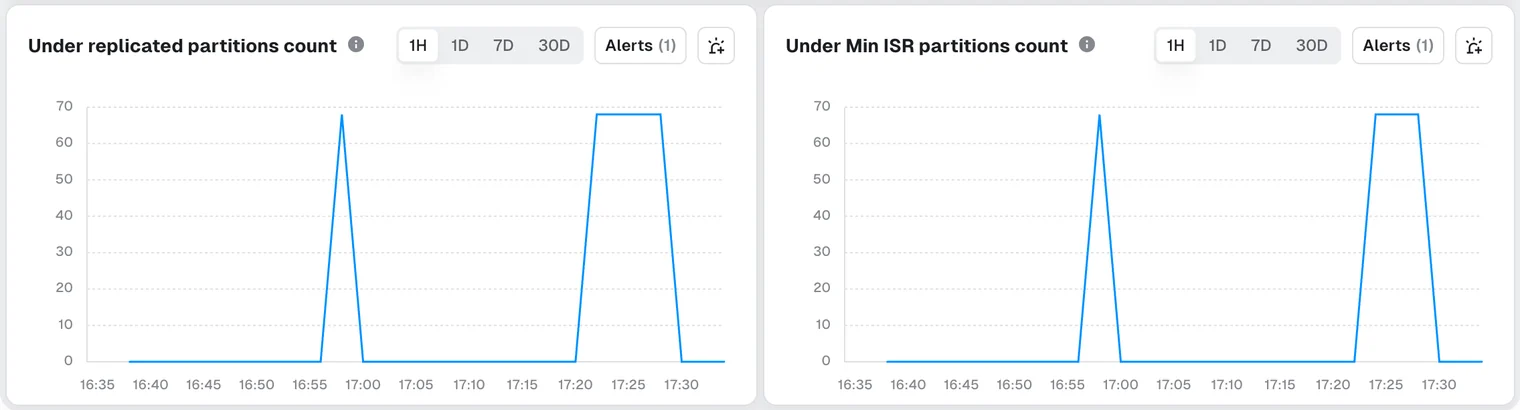
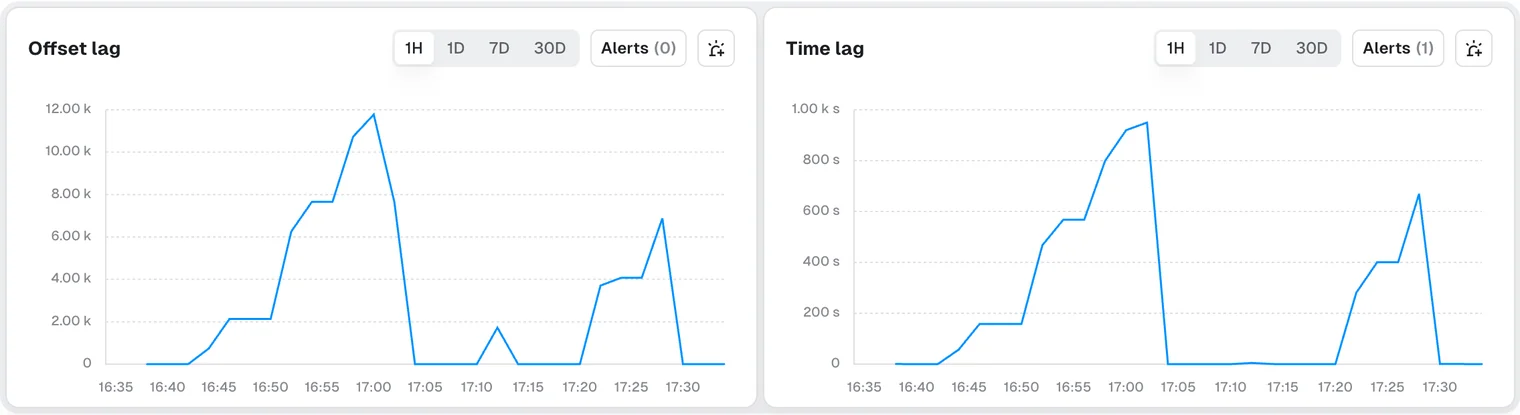
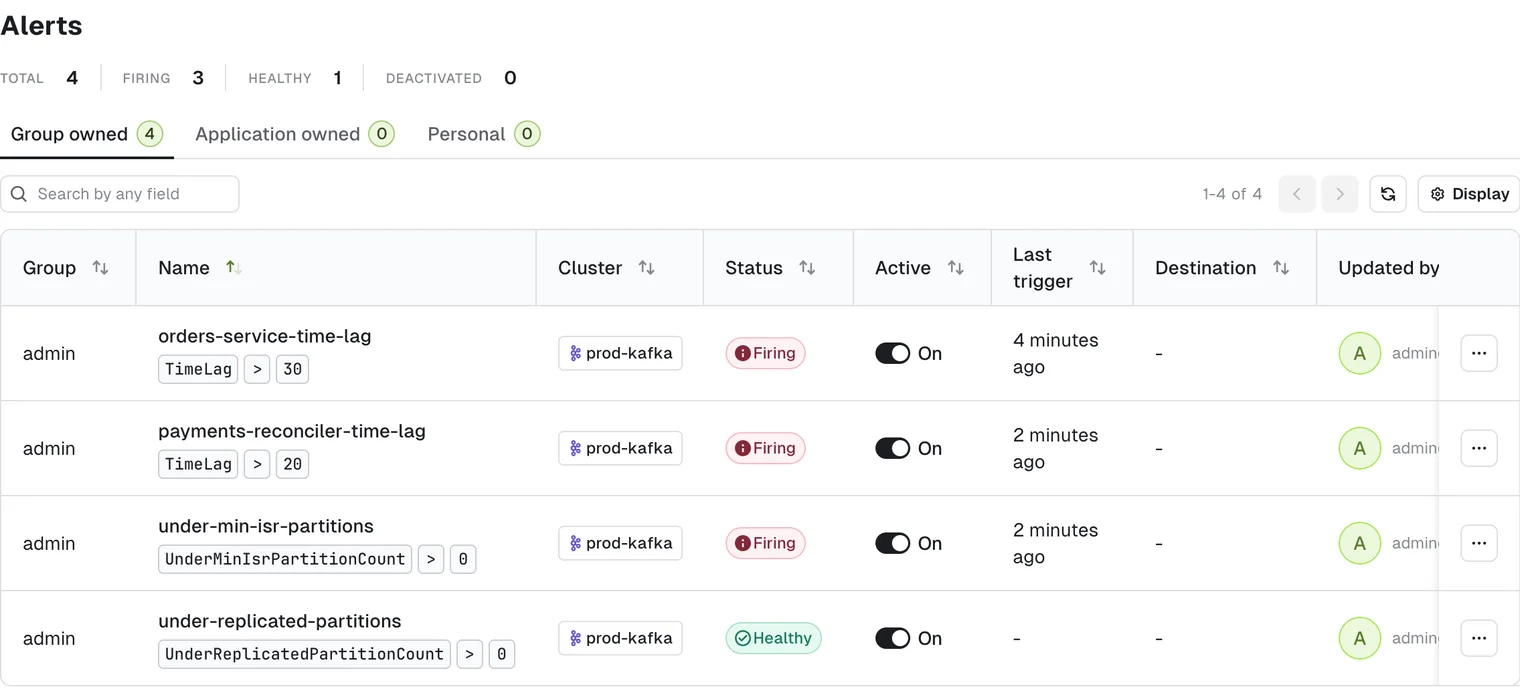
Each alert belongs to a group, an application from federated ownership or a person, and goes to Slack, Teams, email or a webhook.
Send Lag Alerts to AI Agent Teams
The few metrics worth an alert say whether producers can write and whether consumers keep up, and each one needs a team that acts when it fires.
More of those teams will sit outside the platform team: AI agents read Kafka topics for the latest data.
The teams deploying them will ask how old that data is. The answer is the lag of each agent's consumer group in seconds, read from committed offsets and sent to them.
Talk to us about monitoring your clusters →
Related: Best Kafka Monitoring Tool → · Consumer Lag Alert Thresholds → · Kafka Cluster Monitoring and Metrics →