
A compacted topic keeps the latest record for each key instead of deleting records after a set time. A service that reads it from offset 0 ends with the current value of every key, then keeps consuming: a table you can replay.
It has no lookup by key, no index and no query. The broker removes old values only when its cleaner runs over them, by default a week or more later on a quiet topic.
How Compaction Works
A regular topic deletes by age: with cleanup.policy=delete, segments go once they're older than retention.ms, seven days by default.
With cleanup.policy=compact, a record goes once a newer record with the same key exists further down the log. A record with a null value, a tombstone, deletes its key.
Take a customers topic keyed by customer ID on Kafka 4.3.1, set up to compact within seconds. Six plan changes and a tombstone for c-3 go in, then c-4 106 seconds later:
$ kafka-topics.sh --bootstrap-server localhost:9092 --create --topic customers --partitions 1 \
    --config cleanup.policy=compact --config segment.ms=5000 \
    --config min.cleanable.dirty.ratio=0.01 --config delete.retention.ms=60000
Created topic customers.

$ kafka-console-consumer.sh --bootstrap-server localhost:9092 --topic customers --from-beginning \
    --formatter-property print.offset=true --formatter-property print.key=true

# as written
Offset:0  c-1  {"plan":"free"}
Offset:1  c-2  {"plan":"free"}
Offset:2  c-1  {"plan":"pro"}
Offset:3  c-3  {"plan":"free"}
Offset:4  c-2  {"plan":"team"}
Offset:5  c-1  {"plan":"enterprise"}
Offset:6  c-3  null

# after c-4 and the first cleaner pass
Offset:4  c-2  {"plan":"team"}
Offset:5  c-1  {"plan":"enterprise"}
Offset:6  c-3  null
Offset:7  c-4  {"plan":"free"}
The cleaner dropped four records, and what's left follows four rules:
- Offsets never change. Nothing is renumbered, and a consumer whose committed offset was 2 resumes at the next record that exists.
- Order holds. The cleaner never reorders records within a partition.
- Tombstones survive the pass. A consumer reading later still learns that
c-3was deleted. - The active segment is untouched. The cleaner skipped it, so
c-4stays as written.
The cleaner rewrites the dirty section, the closed segments written since its last pass, into a clean section with one record per key:
customers: superseded records go and their offsets stay empty.Keyless Records Are Rejected
Compaction needs a key to decide what to keep, so the broker refuses a record without one. A plain value sent to customers fails:
org.apache.kafka.common.InvalidRecordException: Compacted topic cannot accept message without key in topic partition customers-0Debezium's schema history topic hits this error when it's created as compacted: Debezium writes that topic without keys and warns when its cleanup.policy isn't delete.
When Compaction Runs
New records go to the active segment, which the cleaner never touches. The broker replaces it with a fresh one, a roll, once it's older than segment.ms (seven days) or larger than segment.bytes (1 GiB), and only when a record arrives.
In the run, segment.ms was five seconds, yet all seven records stayed for more than a minute and a half. The write of c-4 rolled the segment, and the cleaner compacted it 13 seconds later.
🚫 "A compacted topic holds one record per key."
Only its clean section does. With the defaults, a topic that gets a few updates a day keeps its active segment for seven days, and the cleaner then waits until dirty records make up half of the log.
max.compaction.lag.ms caps that wait: a record becomes cleanable at that age whatever the dirty ratio, and the active segment rolls at that age too, on the next write.
With the ratio at 0.99, a second update to one key was compacted on a topic with max.compaction.lag.ms=10000 and stayed on a topic without it. On a compact-only topic, no other setting bounds how long an overwritten or deleted value survives.
Compaction Settings
Each topic setting falls back to a broker setting, and --describe --all shows both:
$ kafka-configs.sh --bootstrap-server localhost:9092 --entity-type topics --entity-name defaults-probe \
    --describe --all | grep -E 'cleanup|dirty|delete.retention|max.compaction'
  cleanup.policy=compact sensitive=false synonyms={DYNAMIC_TOPIC_CONFIG:cleanup.policy=compact, DEFAULT_CONFIG:log.cleanup.policy=delete}
  delete.retention.ms=86400000 sensitive=false synonyms={DEFAULT_CONFIG:log.cleaner.delete.retention.ms=86400000}
  max.compaction.lag.ms=9223372036854775807 sensitive=false synonyms={DEFAULT_CONFIG:log.cleaner.max.compaction.lag.ms=9223372036854775807}
  min.cleanable.dirty.ratio=0.5 sensitive=false synonyms={DEFAULT_CONFIG:log.cleaner.min.cleanable.ratio=0.5}
Defaults match the topic configuration reference. The starting values suit a small state topic:
| Setting | Default | Starting point, small state topic | Effect |
|---|---|---|---|
cleanup.policy | delete | compact | Delete by key; compact,delete adds retention.ms |
min.cleanable.dirty.ratio | 0.5 | 0.1 | Dirty share that starts a pass; lower costs CPU and I/O |
segment.ms | 7 days | 5 minutes | Age that rolls the active segment |
segment.bytes | 1 GiB | default | Size that rolls the active segment |
delete.retention.ms | 1 day | above your slowest replay | Minimum time a tombstone stays |
min.compaction.lag.ms | 0 | default | Minimum age before compaction |
max.compaction.lag.ms | never | 1 day | Age that forces compaction and a roll |
segment.ms means more, smaller segments. On a large or busy topic, raise segment.ms, since max.compaction.lag.ms already bounds how long a superseded value can stay. How Tombstones Expire
A tombstone has to outlive the value it deletes, or a consumer replaying the topic never learns the key is gone.
The cleaner keeps it through the pass that removes the value and drops it on a later pass, after delete.retention.ms. In the run (60 seconds), that later pass came only once new writes made the log dirty again:
Offset:5  c-1  {"plan":"enterprise"}
Offset:7  c-4  {"plan":"free"}
Offset:8  c-2  {"plan":"pro"}
Offset:9  c-5  {"plan":"free"}
A consumer replaying from the start that takes longer than delete.retention.ms to reach the end misses the tombstone and keeps c-3 for good:
"It is possible for a consumer to miss delete markers if it lags by more than delete.retention.ms."
Apache Kafka documentation, Log Compaction
What a Compacted Topic Lacks
Each thing a database does with a key is weaker on a compacted topic, or missing:
| You need | A compacted topic offers |
|---|---|
| Read one key | A scan of the key's partition from its first offset |
| Find by another field | A scan of every partition |
| A secondary index | Nothing |
| Delete a key | A tombstone, visible for delete.retention.ms |
| Update only if unchanged | Nothing: two writes to one key both land, and the higher offset wins |
| Change several keys atomically | Transactions, which don't check stored values |
| Cheap storage for old data | Nothing: tiered storage doesn't support compacted topics |
A compacted topic fits when consumers read the current value of every key:
- CDC changelogs. Keyed by primary key.
- Reference data. Tenants and configuration.
- Kafka Streams state. The changelog behind each store.
- Entity snapshots. Published for downstream teams.
Building a Local State Store
Kafka's group coordinator loads __consumer_offsets into memory, and Kafka Connect and Schema Registry do the same with their compacted topics. In an application, Kafka Streams does it with a KTable materialized into a state store:
KTable<String, String> customers = builder.table(
    "customers",
    Consumed.with(Serdes.String(), Serdes.String()),
    Materialized.as("customers-store"));

// once the instance is RUNNING
ReadOnlyKeyValueStore<String, String> store = streams.store(
    StoreQueryParameters.fromNameAndType("customers-store", QueryableStoreTypes.keyValueStore()));

store.get("c-1");  // {"plan":"enterprise"}
store.get("c-3");  // null: the tombstone deleted it
The store is a local RocksDB database, so a lookup never leaves the process. It has four costs:
- A second copy. Streams writes a compacted changelog,
customer-lookup-customers-store-changeloghere, unlesstopology.optimization=allreuses the source topic. - A rebuild on a new machine. An instance without local state replays the topic before serving (why restore is slow).
- Partition-local keys. A
KTableinstance holds only its partitions' keys, and routing a lookup is yours to build. AGlobalKTableloads everything into every instance: fine for small data such as tenants. - Late reads of your own writes. After an update, the store returns the old value until the consumer catches up.
The topic stays the source of truth; each store is a rebuildable copy:
For a service that needs every tenant, a GlobalKTable over a compacted tenants topic lets each instance load the current state from Kafka alone at startup.
Policies for Compacted Topics
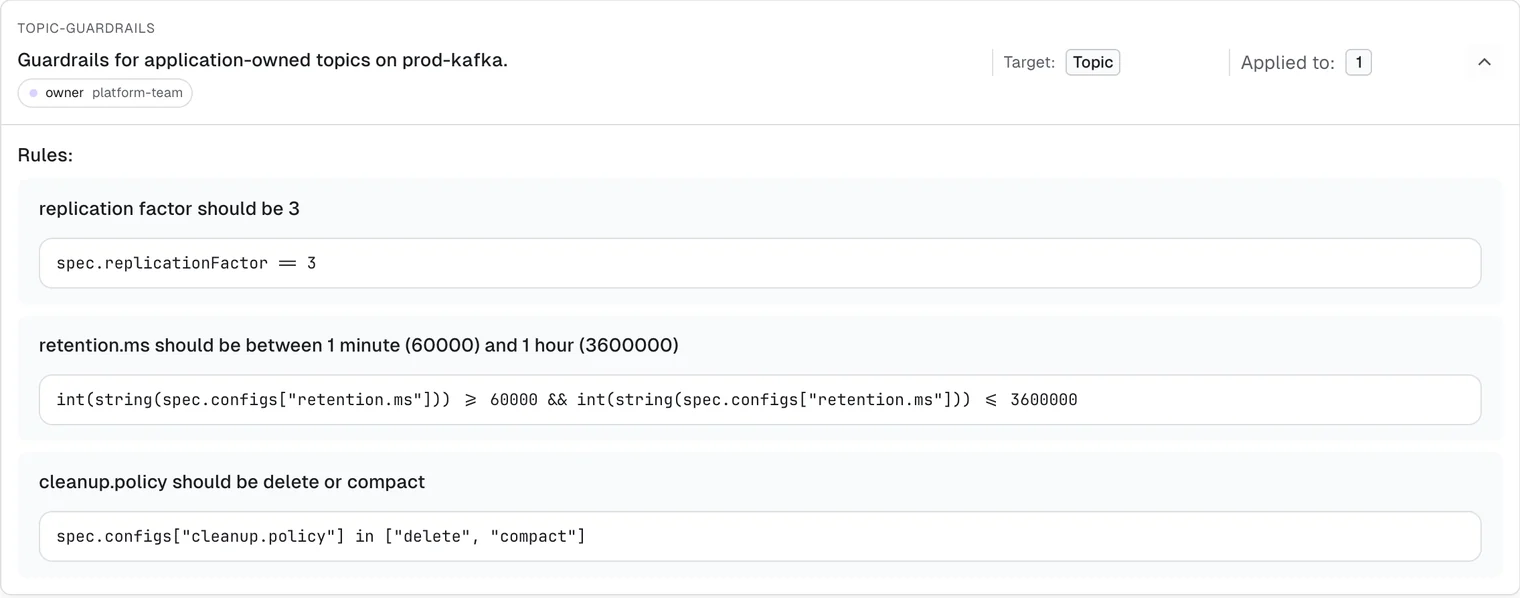
In Conduktor Console, a platform team links a resource policy to a cluster or an application, and Console refuses to create or update a topic whose settings fall outside your range, such as a delete.retention.ms shorter than your slowest replay.
Erasure on Compacted Topics
A compacted topic is a durable, replicated table that any service can replay to rebuild current state. Lookups, indexes and queries belong in a store built from it, which you can rebuild at any time.
A compacted users topic holds personal data. When one of those users asks to be erased, the privacy team or an auditor will ask how long their old records stay readable after the tombstone.
On a compact-only topic, they stay until the cleaner's next pass over their segment, and only max.compaction.lag.ms makes that pass due at a set age.
Talk to us about Kafka state on your clusters →
Related: GDPR and Kafka: Right to Erasure → · KStream vs KTable vs GlobalKTable Explained → · Event Sourcing with Kafka: Patterns and Pitfalls →