Schemaless data structures emerged from the NoSQL wave of the 2010s. Relational databases couldn't easily scale or accommodate different data formats. The solution: do away with schemas altogether.
The results were mixed. Ingesting all types of data without schema validation simply delays the problem, forcing teams to clean up messy data after the fact. Schemaless databases needed validation mechanisms, or they would break downstream applications.
Kafka Transmits Bytes, Not Schemas
Kafka was designed to move data quickly and asynchronously between producers and consumers. It supports JSON, Protobuf, Avro, CSV, strings, XML, and more. Enforcing schemas would slow things down, so Kafka transmits data as byte arrays and ignores the content within.
This flexibility is valuable for prototyping, spinning up test environments, or internal projects where schema enforcement adds friction. Kafka's format-agnostic design makes it an excellent data backbone for connecting stores, sources, and sinks across any digital environment.
When Schema Enforcement Becomes Necessary
Skipping schema validation works for experiments and internal communication. In production, you pay for it later.
Incompatible message formats create knock-on effects for downstream applications. An analytics application at a government institution that ingests an age value of 200 years breaks. Engineers must manually comb through data to find the offending record.
Schema enforcement improves observability. Structured data enables searches, queries, troubleshooting, and auditing. Without clear data formats, isolating individual messages by field or value becomes difficult.
Encryption depends on schema too. Developers need to know which fields to obscure and how to monitor data flows for GDPR, HIPAA, or CCPA compliance.
Forward and backward compatibility also requires schema management. If there is no registry to ensure logical schema evolution, applications might not access older or newer data. If an energy provider buys solar panels that generate new metrics with different firmware, the schema must be updated, or analytics and AI lose key context.
How Schema Registries Prevent Breaking Changes
Some Kafka distributions include schema enforcement tools. Confluent's Schema Registry is the most popular. It centrally stores and versions schemas, validates data during production and consumption, and checks for compatibility. This enables schema evolution so old and new devices can work together.
Schema Registry provides a solid foundation for implementing contracts and data structures throughout your Kafka environment. But for large, complex environments that require guaranteed data quality, additional tooling fills the gaps.
How Data Quality Policies Validate Data Before It Enters Pipelines
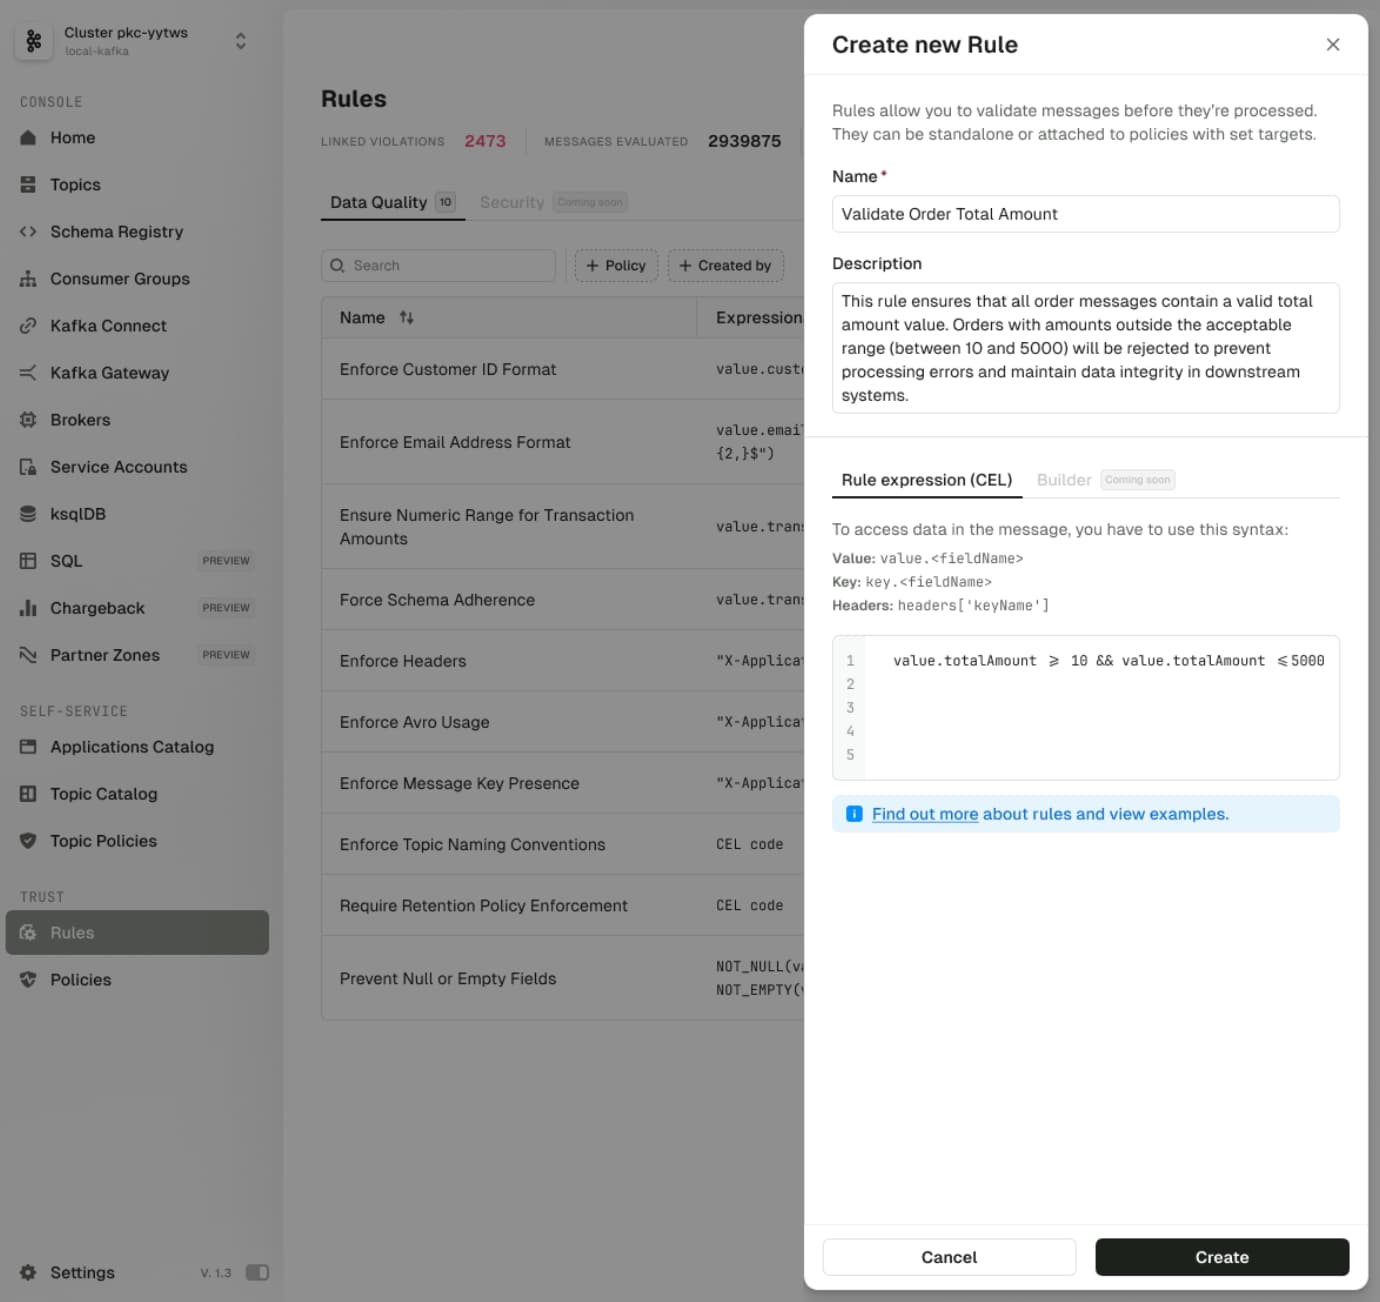
In Conduktor Console, teams write rules (CEL expressions or JSON Schema) and attach them to topics through data quality policies. With Conduktor Gateway in the path, records are checked before they're written, so malformed data can be blocked before it enters the system.
For the age validation problem: a team could write a rule that limits age values to 100 (or 115 at maximum). Policies need no code changes in existing producers, and they can start by reporting violations before anything is blocked.
Each policy shows its violations: how often they happen, on which topic, and from which service account. A spike in violations means something is broken on the producer side and is worth investigating.
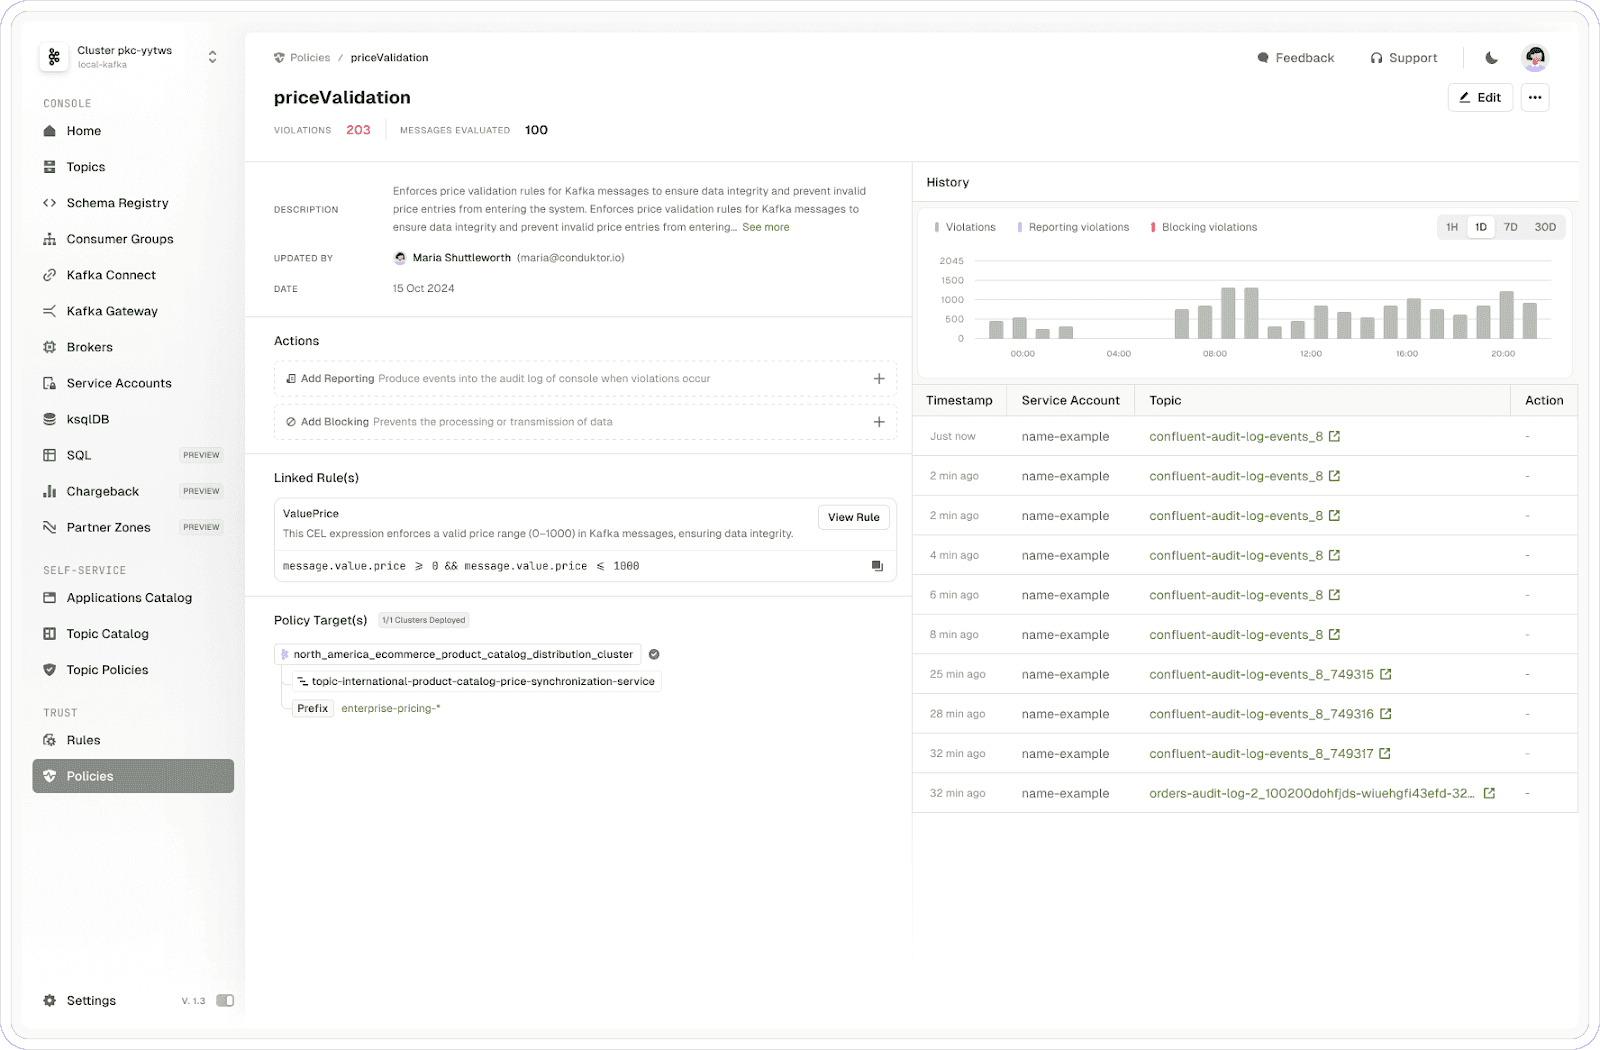
Policies work on schemaless topics. A JSON Schema Rule carries its schema inline, and a CEL rule checks fields directly, so malformed fields or payloads can be validated and blocked without a Schema Registry.
Schema Requirements in Production Kafka
Kafka's flexibility comes from ignoring data schema. Real-world production shows that structure is essential for data quality, observability, and compliance at scale.
Schema Registry validates and evolves schemas but may not include monitoring, auditing, or alerting. It may not work with schemaless topics.
Conduktor data quality policies validate data proactively: they apply custom rules, block bad messages before they enter pipelines, and work on schemaless topics. Even if Kafka doesn't require schemas, your applications and operating conditions do.
To see data quality policies on your own topics, talk to us.