AI is only as good as its last input. Low quality data (broken or missing schema, inaccurate or incomplete fields, inconsistent formatting, range value violations) leads to hallucinations, model drift, and degraded accuracy.
Confluent's latest data streaming report surveyed 4,000 tech leaders. 68% cited data quality inconsistencies as their greatest data integration challenge. 67% cited uncertain data quality, a related problem that stems from lack of visibility and monitoring.
Proactive vs Reactive: Filter Bad Data or Clean Up After
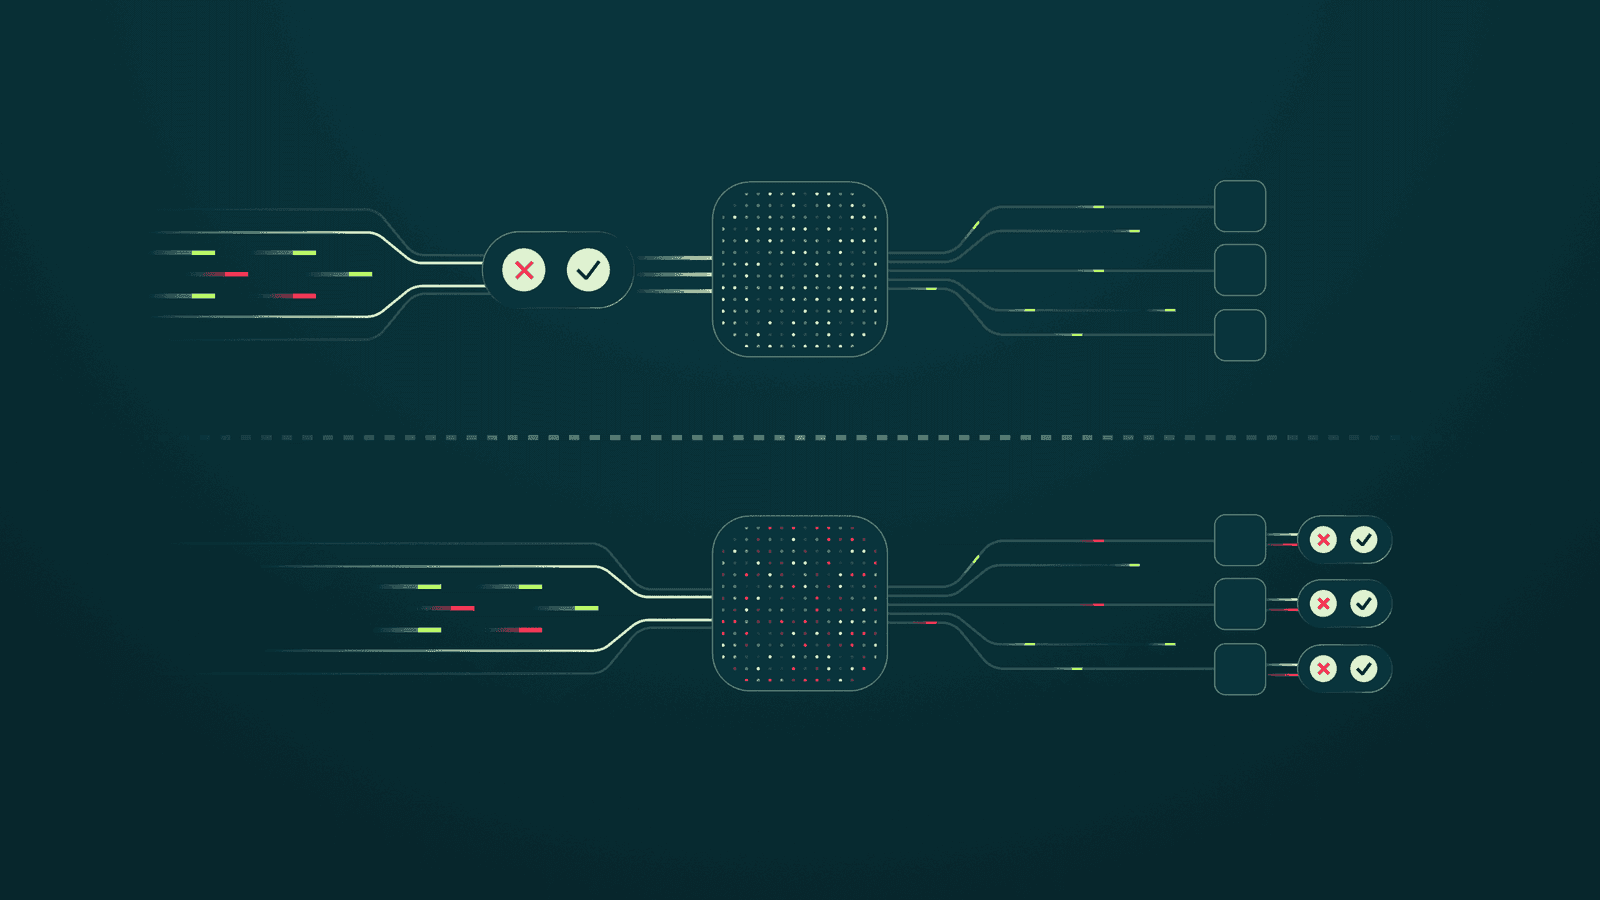
Organizations can ensure data quality in two ways. Proactive: filter and stop inconsistent data from entering the environment. Reactive: clean up errors after ingestion.
These approaches require different tools.
The proactive approach shifts left, moving upstream toward the data source. This requires streaming-compatible tools for schema enforcement, policy rules, and quality gates.
The reactive approach shifts right, moving downstream toward applications like AI and analytics. The downside is that by the time issues are detected, the damage is done. Dashboards display inaccurate metrics. AI models deliver flawed predictions. Decision makers lack key context.
The reactive approach also requires significant cleanup effort. Engineers must root out poor quality data, trace its lineage, identify where it originated, how it was transformed, and which applications it reached. This means investigating logs, audit trails, and coordinating across teams. A long, error-prone process that pulls engineers from core work.
The 1:10:100 rule quantifies this: for every dollar spent validating data at the source, it costs 10 dollars to fix at the transformation stage and 100 dollars at the point of consumption. Costs balloon as issues move downstream.
Real-Time AI Requires Proactive Data Quality
As AI becomes real-time (fraud detection, personalized retail, autonomous vehicles) inputs must shift from batch to streaming ingestion. Proactive data quality becomes critical given the stakes: compromised credentials, lost revenue, safety issues. As Conduktor CTO Stéphane Derosiaux puts it, "it's garbage in, disaster out."
Time-sensitive applications cannot rely on post-ingestion cleanups. Waiting means flawed data pollutes customer-facing experiences, operational systems, and AI pipelines before detection. For organizations relying on real-time insights for competitive advantage, shifting quality enforcement right is too risky.
For enterprise leaders, poor data quality creates business risk. It drives up operational costs, clouds decision making, and undermines overall success. Untrustworthy data leads to untrustworthy AI, weakening product launches, customer experiences, and compliance postures.
Enforce Data Quality Policies at the Source
Organizations must introduce quality enforcement as early as possible, before bad data affects downstream applications.
Conduktor Console holds data quality policies: rules (CEL expressions or JSON Schema) attached to topics. With Conduktor Gateway in the path, they let teams:
- Enforce schema and payload rules at the source
- Prevent bad data from reaching downstream applications
- See violations by policy, topic, and service account
Some streaming technologies devolve governance to individual producers and teams. Decentralization sounds good in theory. In practice, it creates friction. Every team must implement identical configurations and procedures for data quality validation. Mistakes create gaps. Synchronizing processes across many producers is time-consuming and expensive, especially in large environments with clusters feeding data asynchronously.
A policy is defined once in Console and applies to every producer writing to its topics, so no team has to reimplement the checks.
Talk to us to see data quality policies on your topics.