
How to Build Idempotent Kafka Consumers
Kafka deduplicates what producers send: since Kafka 3.0, producers are idempotent by default, and the broker drops a batch a producer retries. It does nothing of the kind for consumers.
Deduplicating on the consumer side is your job, and no Kafka setting does it for you: only your code knows whether a record's side effect (a row, a charge, an email) already happened. Such are the joys of distributed systems.
Skip it, and one order gets charged twice: a consumer writes the charge, crashes before telling Kafka the record is done, and the consumer that takes over charges again. That's at-least-once delivery, the consumer default: the next consumer resumes from the last committed offset.
An idempotent consumer makes the second delivery change nothing. It identifies each message by a stable key and writes that key in the same transaction as its side effect, so a replayed record finds its key already stored.
The steps to build an idempotent Kafka consumer:
- Choose an idempotency key. One value per business operation, the same on every resend and replay.
- Store the key with the write. The key and the side effect commit together, or the side effect is itself idempotent.
- Commit offsets after the write. A crash in between replays the record, and the replay finds its key.
- Keep keys past
retention.ms. A replay reaches back to the oldest record the topic still holds. - Test a crash and concurrent duplicates. Both must leave one result per record.
Choose an Idempotency Key
A record reaches your consumer more than once in four cases:
Producer resends
The acknowledgement gets lost and the producer sends again. Idempotence drops that retry, but a restarted producer writes a second copy.
Consumer crashes
Your consumer writes to the database, then crashes before committing the offset. Kafka redelivers from the last committed offset.
Rebalances
A consumer dies or stalls past max.poll.interval.ms. Its partitions move to another member, which starts from the last commit.
CDC relay restarts
A transactional outbox relay such as Debezium publishes rows from the database log. After a crash, it may publish some again.
🚫 "We set
enable.idempotence=true, so our consumers won't see duplicates."
The idempotent producer, on by default in the Java client since Kafka 3.0 (librdkafka clients leave it off), deduplicates retried batches within one session. The broker drops a batch whose sequence number it already wrote for that producer ID.
A restarted producer gets a new ID, and a new send() after delivery.timeout.ms expires gets a new sequence number: either way the broker writes a second copy. Two sessions that send the same payment land it twice:
$ kafka-console-producer.sh --bootstrap-server localhost:9092 --topic payments \
    --reader-property parse.key=true --reader-property key.separator=:    # run twice
INFO [Producer clientId=console-producer] ProducerId set to 5 with epoch 0
INFO [Producer clientId=console-producer] ProducerId set to 6 with epoch 0
$ kafka-console-consumer.sh --bootstrap-server localhost:9092 --topic payments \
    --from-beginning --formatter-property print.offset=true --formatter-property print.key=true
Offset:0	pay-1002	{"paymentId":"pay-1002","amountCents":1350}
Offset:1	pay-1002	{"paymentId":"pay-1002","amountCents":1350}
Crash and rebalance duplicates never pass through the producer, so the key has to travel with the message. It must be unique per logical operation, stable across retries, and ideally generated by the producer. Three options, from safest to most fragile:
- Client-generated UUID. Created where the business action starts, carried in the payload or a header. With an outbox, the outbox row's ID, which Debezium puts in the
idheader. - Composite business key.
customerId:orderId:timestamp, with the timestamp from the event payload: the produce timestamp changes on a resend. - Kafka coordinates.
topic-partition-offsetbreaks on a replay from another topic, a producer resend or a move to another cluster.
Store the Key With the Write
An idempotent consumer tracks which messages it has processed:
public void consume(ConsumerRecord<String, OrderEvent> record) {
    String key = extractIdempotencyKey(record);

    if (deduplicationStore.hasProcessed(key)) {
        log.debug("Skipping duplicate: {}", key);
        return;
    }

    processOrder(record.value());
    deduplicationStore.markProcessed(key);
}
The side effect and the key have to commit together. As two separate writes, a crash between them loses the message or processes it twice:
Three patterns close that window, each with the key in a different place and a different cost per record:
| Pattern | Where the key lives | Extra work per record | Best for |
|---|---|---|---|
| Database constraint | In the business transaction | One indexed insert | CRUD services, existing DB |
| Redis SETNX | In Redis, outside the transaction | One Redis round trip | Side effects that are themselves idempotent |
| Natural upsert | In the row (event_version) | None | State replacement events |
An email or a payment API call can't roll back with a database row: pass the idempotency key to the callee, in an Idempotency-Key header for APIs that support one (passing the key downstream).
Pattern 1: Database Constraint
A primary key on the idempotency key rejects the second insert:
CREATE TABLE processed_messages (
    idempotency_key VARCHAR(255) PRIMARY KEY,
    processed_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP
);
The consumer inserts the key and the business row in one transaction:
@Transactional
public void processOrder(ConsumerRecord<String, OrderEvent> record) {
    String key = extractIdempotencyKey(record);

    int inserted = jdbcTemplate.update(
        "INSERT INTO processed_messages (idempotency_key) VALUES (?) ON CONFLICT DO NOTHING",
        key);
    if (inserted == 0) {
        log.info("Duplicate detected: {}", key);
        return;
    }
    orderService.createOrder(record.value());  // same DataSource, same transaction
}
With @Transactional, a failed order creation rolls the deduplication record back with it. ON CONFLICT DO NOTHING returns 0 rows on a duplicate instead of throwing (INSERT 0 0 in psql).
Catching a unique-violation exception inside the transaction doesn't work. In PostgreSQL the failed statement aborts the whole transaction: the next statement returns current transaction is aborted, commands ignored until end of transaction block, and COMMIT rolls back.
With JPA, the insert may only flush at commit, outside your try.
Two consumers can also process the same record at once: a consumer evicted for exceeding max.poll.interval.ms keeps working on its batch while the partition's new owner starts on the same records. The primary key handles it, because the second insert waits on the unique index:
On PostgreSQL 17, the second session stayed blocked until the first committed, then returned INSERT 0 0 (or INSERT 0 1 when the first rolled back).
Don't add a SELECT before the INSERT: that check-then-insert is the race. Under REPEATABLE READ or SERIALIZABLE, the second transaction fails with could not serialize access due to concurrent update instead and must be retried.
The table grows by one row per message and becomes a write hotspot under high load.
Pattern 2: Redis SETNX
For higher throughput, use Redis with SETNX:
public boolean tryProcess(String idempotencyKey) {
    Boolean wasSet = redis.opsForValue()
        .setIfAbsent("dedup:" + idempotencyKey, "1", Duration.ofDays(14));
    return Boolean.TRUE.equals(wasSet);
}
It's one SET ... NX with an expiry: the first caller gets OK, later ones nil until the key expires. Keep the TTL longer than your replay window.
Redis has four weak points:
- Not in the transaction. A crash between the Redis write and the database write skips the message (key first) or processes it twice (key last).
- Restarts. Redis 7.4 defaults to
appendonly no, so a crash loses the keys since the last snapshot. Turn on AOF withappendfsync everysec. - Failover. Replication is asynchronous, so a failover can lose the latest keys.
- A new dependency. When Redis is down, the consumer can't check keys and stops.
Use it only as a fast first filter in front of a side effect that is itself idempotent: an upsert, or an API call that carries the key.
Pattern 3: Natural Idempotency
When the consumer replaces state with an upsert, you may not need a deduplication store:
INSERT INTO inventory (product_id, quantity, event_version)
VALUES (?, ?, ?)
ON CONFLICT (product_id)
DO UPDATE SET quantity = EXCLUDED.quantity, event_version = EXCLUDED.event_version
WHERE inventory.event_version < EXCLUDED.event_version;
The WHERE clause stops out-of-order events from overwriting newer data, which a key check can't: a late, older event carries its own key. Replaying version 1 after version 2 returns INSERT 0 0, and the row keeps version 2's quantity.
Ordering per entity comes from the record key: the outbox event router keys each record by its aggregate ID, so one order's events stay in sequence on one partition. The version guard covers what arrives late anyway, such as a replay.
An upsert doesn't work for delta operations ("add 10 to quantity") or side effects (sending emails).
Commit Offsets After the Write
Commit the offset after the database transaction commits. Committing before processing avoids the replay but loses the record on a crash instead.
On Kafka 4.3.1, with a consumer that has no key check, commits every five records and is killed after writing offset 7, the partition stays with the dead consumer until its session expires:
The orders table ended with 13 rows for 10 orders. The 45 seconds are the default session.timeout.ms, the time the group coordinator waits for a heartbeat before it reassigns the partition.
Kafka transactions don't replace the key. They commit consumed offsets and produced records together, and they can't include a database write or an API call.
They need transactional producers, a transaction coordinator on the brokers and read_committed consumers downstream, so they pay off when the output is another Kafka topic (when exactly-once is worth the cost).
Keep Keys Past retention.ms
A duplicate that arrives after its key expired is processed as new, so the window must outlast the slowest redelivery:
- Crash and rebalance replays arrive when the partition gets an owner again: 45 seconds after a crash (
session.timeout.ms), or when a lone consumer comes back. - Replays you start, an offset reset or a reprocessing job, reach the oldest record still in the topic: up to
retention.msplussegment.ms, since Kafka deletes whole segments. - Dead-letter re-drives arrive when someone replays the dead-letter topic, often days later (sizing the window).
A window of retention.ms plus segment.ms, 14 days with the defaults (seven each), covers every record still in the topic.
When you reset offsets to rebuild a table, the stored keys make the consumer skip the records you meant to reprocess: clear the keys for that consumer together with the table.
Test a Crash and Concurrent Duplicates
Process the same record twice and check for one result:
@Test
void shouldHandleDuplicateMessages() {
    String key = UUID.randomUUID().toString();
    ConsumerRecord<String, OrderEvent> record = createRecord(key);

    processor.process(record);
    processor.process(record);

    assertThat(orderRepository.findAll()).hasSize(1);
}
Then kill the consumer between the database commit and the offset commit, and let another member take the partition. With the Pattern 1 key check, the same crash run ends like this:
18:57:43  consumer-a  killed (SIGKILL) before committing offsets 5-7
18:57:44  consumer-b  started, joining group orders-writer
18:58:28  consumer-b  assigned orders-0 (committed offset 5)
18:58:28  consumer-b  offset 5  ord-1005  duplicate, skipped
18:58:28  consumer-b  offset 6  ord-1006  duplicate, skipped
18:58:28  consumer-b  offset 7  ord-1007  duplicate, skipped
18:58:28  consumer-b  offset 8  ord-1008  inserted
18:58:28  consumer-b  offset 9  ord-1009  inserted
The table holds 10 rows for 10 orders. Test concurrent duplicates too: two threads processing the same record at once must still leave one row, and a single-threaded test never reaches the blocking insert.
Conduktor Gateway and Console
Conduktor Gateway sends your consumers duplicates on demand: its duplicate-messages interceptor delivers a percentage of records twice, on fetch only (target: CONSUME, so Kafka stores nothing extra) or on produce.
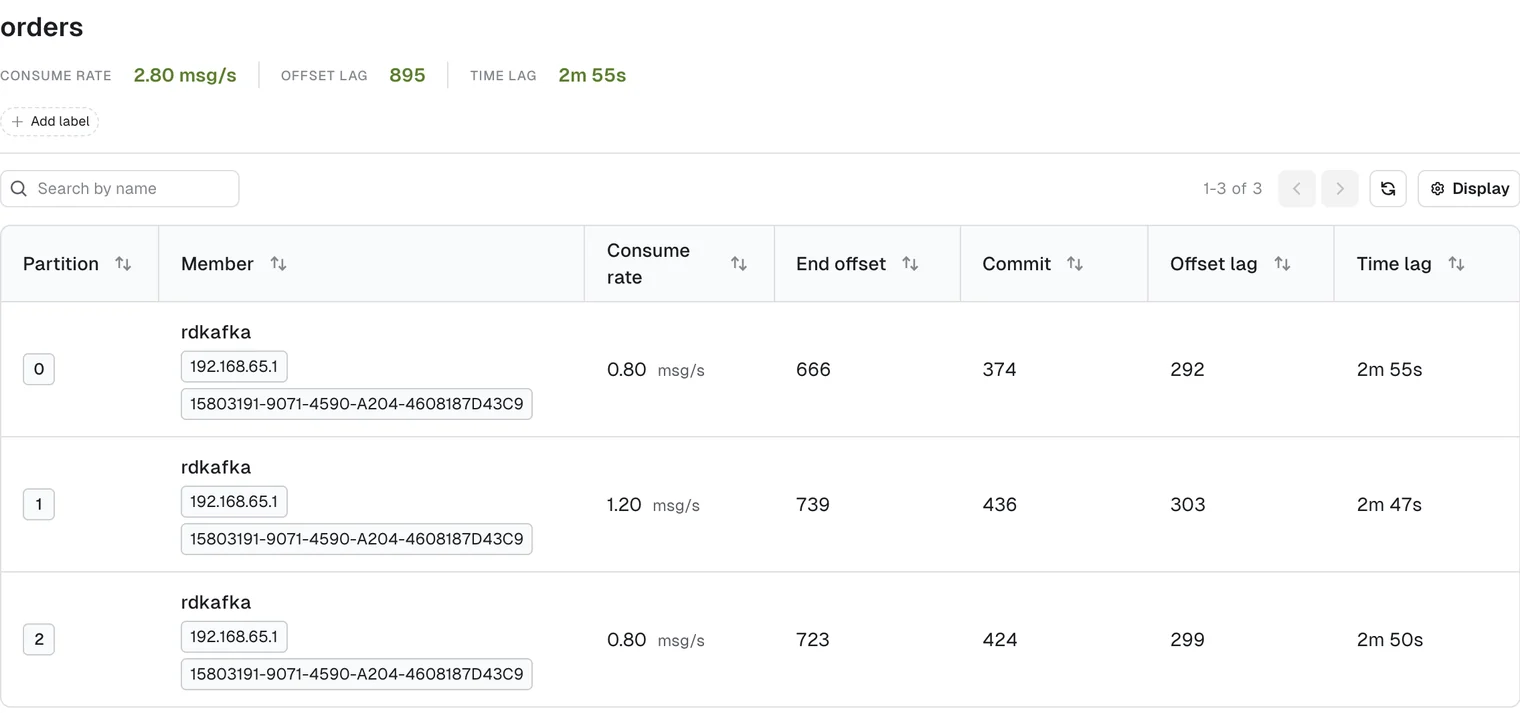
Conduktor Console shows each consumer group's committed offset, end offset and lag per partition: the range a crash replays.
Effectively Exactly-Once
Kafka redelivers whatever a consumer processed and didn't commit, and no producer or broker setting changes that for a consumer that writes to a database. At-least-once delivery plus an idempotent consumer gives effectively exactly-once processing.
Finance asks for that guarantee: reconciliation matches orders against the payment provider, and a charge written twice shows up there.
Teams connecting AI agents to Kafka events will need it too. An agent that reads an order and calls a refund API has a side effect outside any database transaction, and a redelivered event repeats the call unless the key travels with it.
Talk to us about testing your consumers against duplicates →
Related: Kafka Exactly-Once: When It Works and When It Doesn't → · Kafka Offset Management: How Consumer Groups Track Progress → · Chaos Engineering for Kafka →