
"Our Kafka latency is 5 ms" tells you nothing about whether your users are happy.
An average hides the requests people complain about. The slowest 1% can take 100 times longer than the median, and those are the ones that turn into tickets.
Allegro's Kafka team saw exactly that: single-digit-millisecond medians on produce requests, while p99 reached 1 second and p999 3 seconds. Moving brokers to XFS cut the produce requests over their 65 ms SLO by 82%.
A latency number means something only with its percentile (p50, p99 or p999), its two endpoints (producer to broker, or end to end including your processing) and the window it covers. Benchmarking Kafka means reading p99 and p999: the mean says nothing about the tail.
What p99 and p999 Mean
A percentile counts records. p99 is the latency 99% of records beat, so one record in 100 is slower, and p999 (also written p99.9) leaves one in 1,000 above it. At a steady rate, that's a fixed number of slow records:
| Percentile | Records slower than it | At 5,000 records/s |
|---|---|---|
| p50 | 1 in 2 | 2,500 per second |
| p99 | 1 in 100 | 50 per second |
| p999 | 1 in 1,000 | 5 per second |
--warmup-records 25000, printed two summaries of the same run: 150000 records sent, 4999.333422 records/sec (4.88 MB/sec), 6.75 ms avg latency, 354.00 ms max latency, 3 ms 50th, 5 ms 95th, 229 ms 99th, 300 ms 99.9th.
125000 steady state records sent, 4998.600392 records/sec (4.88 MB/sec), 2.49 ms avg latency, 9.00 ms max latency, 3 ms 50th, 5 ms 95th, 6 ms 99th, 7 ms 99.9th.With the warm-up records counted, p99 is 229 ms; without them, 6 ms. The median is 3 ms in both.
At Allegro, the slow produce requests were waiting on ext4 journal commits. One slow write could cascade into many slow requests, and the team traced individual requests to find it:
"p99 and p999 analysis is sometimes not enough."
Allegro Tech Blog
Where a Record Spends Time
Between send() and the consumer's code, a record can wait in four places:
acks=all the producer waits for step 3. The consumer waits for it whatever acks is set to, because it reads only up to the high watermark.Each wait has its own settings:
- In the producer. A batch leaves when it reaches
batch.sizeor afterlinger.ms(5 ms by default). Past what the brokers absorb, batches queue inbuffer.memory. - On the leader. The request waits for a handler thread, then for the append to the log. The OS flushes to disk, but the append still waits when the file system blocks, as at Allegro.
- For the followers. With
acks=all, the leader answers the producer only after every replica in the in-sync replica set (ISR) has fetched the batch. - In the consumer. A consumer reads only up to the high watermark, the offset every in-sync replica has reached. Then your code processes the record before the next
poll().
On a healthy cluster, these settings move latency by a few milliseconds. The seconds in p99 and p999 come from one wait that stalled.
How acks Affects Latency
acks=all Waits for the Slowest ISR Follower
The producer documentation defines acks=all plainly: the leader "will wait for the full set of in-sync replicas to acknowledge the record." The topic setting next to it reads like a quorum:
"Specifies the minimum number of in-sync replicas (including the leader) required for a write to succeed when a producer sets acks to "all""
Apache Kafka, topic configs
🚫 "With three replicas and
min.insync.replicas=2, acks=all waits for the fastest two."
min.insync.replicas is a floor: once the ISR shrinks below it, the leader refuses acks=all writes with NOT_ENOUGH_REPLICAS. Above it, the leader still waits for every replica in the ISR, so one slow follower holds every write.
On the lab cluster, orders has three replicas and min.insync.replicas=2. One follower paused for five seconds during an acks=all run at 2,000 records per second:
$ docker pause broker-3; sleep 5; docker unpause broker-3
40000 records sent, 1997.403376 records/sec (1.95 MB/sec), 667.89 ms avg latency, 5052.00 ms max latency, 6 ms 50th, 4093 ms 95th, 4865 ms 99th, 5034 ms 99.9th.
The median stayed at 6 ms while p95 reached 4.1 seconds. A 20-second pause stalled writes for 8.1 seconds, until the controller fenced the paused broker after broker.session.timeout.ms (9 seconds by default) and the leader dropped it from the ISR.
A follower that keeps heartbeating but falls behind, on a slow disk for instance, stays in the ISR for up to replica.lag.time.max.ms, 30 seconds by default.
The leader's request histograms split a produce request's time into five stages. After the 20-second pause, their maxima read:
kafka.network:type=RequestMetrics,name=<box>TimeMs,request=Produce, read over JMX.The disk append never passed 43 ms; the 8.1 seconds went to waiting for the follower.
acks=1 Hides the Wait From the Producer Only
Latency tuning guides recommend acks=1, and the producer documentation says why: the leader answers after writing to its own log, without waiting for the followers. That holds for the producer.
Take the same five-second pause with acks=1, now with a console consumer timing each record from its CreateTime:
producer: 40000 records sent, 1998.900605 records/sec (1.95 MB/sec), 3.64 ms avg latency, 134.00 ms max latency, 4 ms 50th, 7 ms 95th, 8 ms 99th, 10 ms 99.9th.
consumer: 40000 records consumed, p50 7 ms, p99 4871 ms, p99.9 5052 ms, max 5063 ms
The producer's p99 stayed at 8 ms. The consumer's was 4.9 seconds, the same as with acks=all (4,866 ms), because the paused follower held the high watermark back:
acks=1 acknowledges it at once, and consumers still wait for the follower.For an end-to-end latency target, acks=1 buys nothing while a follower stalls, and it has other effects:
- Durability. If the leader fails after acknowledging a record "but before the followers have replicated it then the record will be lost."
- Idempotence.
acks=1turns it off unless you enabled it explicitly. - Under-min ISR. Below
min.insync.replicas, KIP-966 stops the high watermark: anacks=1record stayed unreadable until the follower came back.
Keep acks=1 for producers that must not block on a follower and can lose a record, such as telemetry.
Low Latency vs High Throughput: Pick One
The settings that cut latency cost throughput, and the reverse. Each one turns in opposite directions for the two goals:
| Setting | For latency | For throughput | What it changes |
|---|---|---|---|
linger.ms | 0 | 5 (default) or more | How long a batch waits to fill before it leaves |
batch.size | 16384 (default) | Larger | How many records one request carries |
compression.type | none (default) | lz4 or zstd | Bytes on the network and disk, against CPU on both ends |
fetch.min.bytes | 1 (default) | Larger | How much data the broker waits for before it answers a fetch, up to fetch.max.wait.ms (500 ms) |
acks isn't one of these dials. As the section above shows, acks=1 speeds up the producer's acknowledgement, and the consumer still waits for every in-sync follower. Which side a topic belongs on depends on who waits for each record:
- Payments, fraud checks, order routing. A customer or a downstream service waits for each record: keep batches short and fetches immediate.
- Clickstream, logs, CDC into a lake. Nobody waits for one event. Records per second and the bytes you pay for decide, so batch and compress.
A topic that needs both needs scale: more partitions and consumers keep each producer and broker below the rate where records start to queue. Past that rate, the unthrottled benchmark below kept each record 489 ms in the producer's send buffer.
Where p99 Latency Comes From
A p99 spike comes from one wait that stalled. Each of these causes stalls one of them, and the broker's stage histograms show which:
| Cause | What waits | What to change | Where it shows |
|---|---|---|---|
| Full send buffer | Records in buffer.memory, before any request | Produce at a rate the brokers absorb, or add partitions and brokers | record-queue-time-max, bufferpool-wait-ratio |
| GC pause on a broker | Every request on that broker | G1 with a fixed heap: the start script sets 1 GB, the Apache docs' example 6 GB | Every stage at once, and the broker's kafkaServer-gc.log |
| Busy request handlers | Requests, for an I/O thread | More num.io.threads (8 by default), leaders spread across brokers | RequestQueueTimeMs, RequestHandlerAvgIdlePercent |
| File system stalls | The append to the leader's log | XFS, as at Allegro, and Kafka data on disks of its own | LocalTimeMs |
| Slow or paused follower | acks=all writes and the high watermark | Fix or replace the broker; it leaves the ISR when fenced or after replica.lag.time.max.ms | RemoteTimeMs, UnderReplicatedPartitions, IsrShrinksPerSec |
| Saturated network | Responses, to be sent | Compression, more num.network.threads (3 by default), faster NICs | ResponseSendTimeMs, NetworkProcessorAvgIdlePercent |
| Consumer rebalance | Processing, while partitions move | Static membership (group.instance.id) or group.protocol=consumer | Lag in seconds, rebalance-latency-max |
Benchmarking Kafka Latency
A benchmark without a throughput limit measures the producer's queue. Unthrottled, the same producer pushed 58,893 records per second, and its own metrics show where the half second went:
$ kafka-producer-perf-test.sh ... --throughput -1 --print-metrics
500000 records sent, 58892.815077 records/sec (57.51 MB/sec), 490.37 ms avg latency, 548.00 ms max latency, 501 ms 50th, 541 ms 95th, 545 ms 99th, 547 ms 99.9th.
producer-metrics:record-queue-time-avg:{client-id=perf-producer-client}  : 489.139
producer-metrics:request-latency-avg:{client-id=perf-producer-client}    : 1.242
Records spent 489 ms on average in the 32 MiB send buffer and 1.2 ms in a request to the broker. Benchmark at the rate production runs, and change one setting per run:
- Report the window and repeat runs. Warm-up moved p99 from 6 ms to 229 ms, and identical runs gave a p999 between 7 and 23 ms.
- Keep one tool across clusters. OpenMessaging Benchmark runs defined workloads and reports publish latency up to p99.9.
- Measure in your consumers. Record processing time minus the record's
CreateTimein a histogram such as HdrHistogram.
Monitor Latency Distributions
A dashboard of averages hides every tail problem. The warm-up run from the first section, summarized the way such a dashboard would:
| Statistic | Value | What it tells you |
|---|---|---|
| Average | 6.75 ms | Looks healthy |
| p50 | 3 ms | The typical record |
| p95 | 5 ms | Still fine |
| p99 | 229 ms | One record in 100 waited 76 times longer than the median |
| p999 | 300 ms | One in 1,000 waited 100 times longer |
50thPercentile through 999thPercentile over JMX on the RequestMetrics histogram of each stage, the …TimeMs names in the table above. Alert when p99 stays above your threshold for several minutes, and on the conditions behind the tail: under-replicated and under-min-ISR partitions, and consumer lag in seconds.
A heatmap of the latency histogram over time shows what a single percentile hides. A p99 that spikes on a fixed period points at something that runs on that period, such as a cron job or a batch consumer catching up.
What Percentiles Can't Show
Percentiles describe a distribution of records, and some latency problems stay outside it:
- A stall on a quiet topic. At one record per second, a two-second stall delays 2 of the hour's 3,600 records and the hourly p999 doesn't move. Count records over a threshold, as Allegro did.
- Several brokers. A cluster's p99 isn't the average of the brokers' p99s: merge the histograms first.
- Two clocks. Latency from
CreateTimesubtracts the producer host's clock from the consumer's, so clock skew shows up as latency. - Your processing. A consumer slower than its input builds lag, and each record waits longer than the last.
- Distance. With followers in other availability zones, every
acks=allwrite and every high watermark move includes the round trip between zones.
Latency Alerts and Chaos Tests
Conduktor Console alerts on the three conditions behind the tail (TimeLag per consumer group, UnderReplicatedPartitionCount, UnderMinIsrPartitionCount) in Slack, Teams, email or webhooks. It collects metrics every 30 seconds, so it tracks sustained stalls; the broker histograms catch a five-second one.
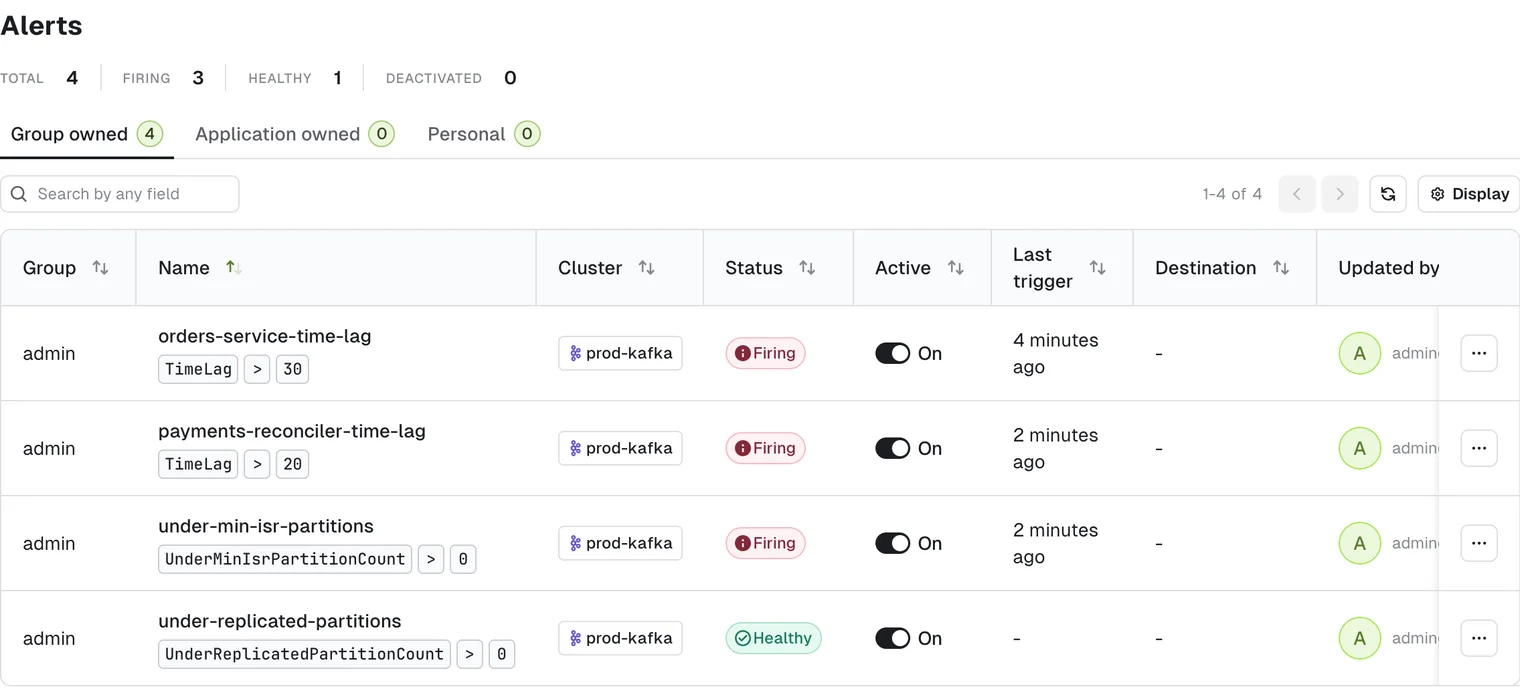
To test your clients' timeouts against a slow tail, Gateway's slow-broker chaos interceptor delays a share of responses by a random time you bound.
Latency SLOs at the Consumer
The latency a customer sees is the consumer's: the time from a record's CreateTime to the code that acts on it. It includes the slowest in-sync follower's wait and the consumer's lag, whatever acks the producer uses, so a producer's p99 can't replace it.
Two kinds of teams will ask the platform for p99 and p999 at their consumers, at production rate and over a stated window, and for an alert when a follower stalls:
- Teams with a consumer SLO. A service that ships orders sets a latency SLO on the records it consumes.
- AI agent rollouts. An agent that answers from the latest events in Kafka is a consumer with a deadline.
Talk to us about latency alerts on your clusters →
Related: Kafka Performance: Measure Before You Tune → · JVM Tuning for Kafka Brokers: G1GC vs ZGC → · Kafka Consumer Lag Alert Thresholds →